Innovative AI Optimization Framework Outperforms Claude Code and Codex by 2.5x Within Identical Compute Parameters

Envision a scenario where your engineering team has deployed an AI tool designed to sift through company documents and address employee inquiries. While it functions flawlessly during development, once in operation, it frequently generates incorrect responses or overlooks critical parameters. Resolving these issues isn’t merely a matter of making simple fixes; it involves arduous trial and error, tweaking various strategies like chunking and retrieval methods, alongside adjusting system prompts. Due to the interconnected nature of these tweaks, pinpointing which specific adjustment rectified the problem can be incredibly challenging.
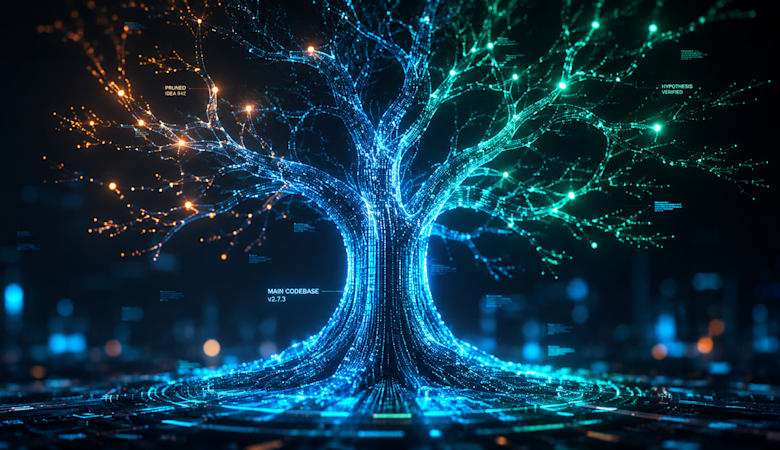
To tackle this dilemma, a group of researchers from Renmin University of China and Microsoft Research has developed Arbor, an innovative framework that transforms the AI-driven research and optimization process from random guesswork into a structured, cumulative learning system. Arbor organizes hypotheses, experiments, and insights in a tree-like structure that allows the system to learn from past failures, leading to more intelligent and verified enhancements over time.
In practical evaluations, Arbor demonstrated performance improvements exceeding 2.5 times that of traditional AI coding agents on real engineering tasks, all while adhering to the same resource constraints.
This advancement in enterprise AI signifies a significant step toward automating the ongoing enhancement of intricate engineering systems.
The Challenges of Autonomous Optimization
As large language models and AI technologies advance, there is an increasing expectation for them to execute more complex tasks, like the autonomous optimization (AO) of software systems, including agent frameworks or model training algorithms.
AO embodies the core process of autonomous research. An AI agent starts with an initial adaptable artifact, such as a machine learning codebase or data pipeline, and a defined goal. Its mission is to iteratively refine this artifact through experimental feedback, all without depending on step-by-step human oversight.
However, the principal hurdle of AO is frequently misidentified. Many engineering teams discover that merely allocating additional time or computing power to optimize a codebase does not yield superior outcomes. According to Jiajie Jin, a co-author of the study, “Automation can keep an AI functioning indefinitely — but a loop does not equate to progress.” He emphasizes that if the objective is ambiguous or if the evaluation metric is easy to manipulate, prolonged automation merely accelerates the generation of undesirable “improvements.”
Jin also points out that complex tasks often require numerous attempts to perfect, and conventional agent frameworks typically lack the essential data structure necessary to maintain continuity. “How can you guarantee that the insights and experience gained from each attempt are preserved, instead of being lost in a scrollback buffer?” he queried. Without such a structure, agents are prone to repeat past errors.
Current agent systems can run numerous experiments for extended periods against well-defined objectives such as code editing, tool invocation, and autonomous testing. However, they treat each attempt independently, lacking the structural framework needed to accumulate and act on learned information.
They also struggle to maintain and compare multiple competing research directions simultaneously. Without this capability, they fail to interpret both successes and failures adequately, hindering the evolution of future exploration, a process essential for cumulative human research.
General coding agents typically rely on conversation history for memory. Given that AO tasks might require extensive dialogue and easily surpass context limitations, these agents find it challenging to retain and leverage factual information over lengthy interactions. Consequently, they lose track of the overall research structure and may become stalled on initial failures or distracted by erratic evaluation outcomes. A solidified memory architecture is necessary to document what paths have been explored, what factual evidence was collected, and how each outcome influences future hypotheses.
Moreover, existing frameworks are susceptible to reward manipulation and overfitting to development metrics, creating the illusion of progress without yielding tangible enhancements in real-world applications.
Lastly, general-purpose coding agents typically rely on a unified working tree for their operations. This design limitation restricts them from testing multiple hypotheses in isolation without corrupting the main codebase or obscuring which hypothesis led to a specific outcome.
The Arbor Framework
Arbor effectively addresses the challenges of AO through a framework that automates the comprehensive exploration, experimentation, and abstraction cycles characteristic of human research. The framework differentiates between the strategic oversight of research and the hands-on coding tasks through two primary components:
The Coordinator: This long-term AI agent operates as the principal investigator. It does not modify the target codebase directly. Instead, it oversees the general state of the optimization research, observes accumulated insights, generates new hypotheses, and decides on subsequent actions based on experimental outcomes.
Executors: These are focused, short-lived AI agents. When the coordinator decides to test an idea, it activates an executor in a separate environment (essentially a fresh git worktree). Each executor is assigned a single hypothesis, responsible for its implementation, evaluation, and report of results back to the coordinator.

The collaboration of these two components hinges on a method termed “Hypothesis Tree Refinement” (HTR). This approach visualizes the research process as a branching tree where each node connects four elements: a hypothesis, an executable artifact, the factual evidence generated, and a distilled insight. This allows the coordinator to simultaneously delve into multiple competing directions without losing its orientation.
The coordinator builds the tree by positioning broad concepts near the trunk, while more specific ideas extend as leaves. This design permits Arbor to explore multiple hypotheses concurrently. If an executor’s test fails, the tree notes the reasons for the failure as a negative constraint, preventing the system from repetitively making the same error.
Consider a typical scenario in enterprise AI: optimizing a Retrieval-Augmented Generation (RAG) pipeline for an internal AI assistant. According to Jin, when a single agent like Claude Code or Codex is tasked with “improving accuracy,” it often implements various changes simultaneously — altering chunking, prompts, and retrieval methods, which complicates tracking the effectiveness of each change. Arbor tackles this by representing each variable as a distinct hypothesis. For instance, chunking, retrieval, and prompts would each be explored separately in distinct git worktrees, leading to clear attribution of results.
When an executor completes its evaluation, the coordinator incorporates the evidence into the tree and updates the higher nodes accordingly. This process ensures that localized observations contribute to a broader understanding that influences future idea generation.
To mitigate reward manipulation and overfitting to development metrics, HTR employs a strict “merge gate.” Even if an executor achieves a high development score, the coordinator initiates a separate worktree test against a holdout evaluator. Only if the artifact demonstrates an actual improvement in test scores does it get merged into the main branch, ensuring that progress is valid.
Arbor is aligned with the concept of “loop engineering,” promoted by figures like OpenClaw creator Peter Steinberger and Claude Code lead Boris Cherny. This approach emphasizes moving beyond single prompts to cultivate iterative cycles (observe, reason, act, verify) that power autonomous agents. However, Jin clarifies, “An unstructured loop can become filled with disorganized, untraceable attempts, resulting in no tangible outcomes and an inability to identify what changed.”
Arbor in Action
The researchers examined Arbor’s effectiveness through an autonomous optimization task suite derived from real-world research contexts and the MLE-Bench Lite benchmark in machine learning engineering. The suite depicted diverse AI development challenges encompassing model training, harness engineering, and data synthesis.
The researchers utilized various backbone models for both the coordinator and executor agents, including Claude Opus 4.6, GPT-5.5, and Gemini-3-Flash, comparing Arbor against other leading coding agents like Codex and Claude Code under equal resource conditions. In the MLE-Bench Lite tasks, Arbor was also pitted against advanced agentic systems such as AI-Scientist, ML-Master, and AIDE.
Arbor consistently surpassed its competitors, achieving superior results across all tasks. It recorded over 2.5 times the average relative improvement compared to Codex and Claude Code. For example, in the BrowseComp task focused on optimizing a search agent, Arbor boosted the held-out accuracy from a baseline of 45.33% to 67.67%, while Codex and Claude Code only managed scores of 50% and 53.33%, respectively. When powered by GPT-5.5, Arbor delivered the best overall performance on the MLE-Bench Lite benchmark.

Arbor also demonstrated resilience against overfitting. For instance, during experiments with the Terminal-Bench 2.0 task, Claude Code recorded a high development score of 75 but dropped to 71 on the held-out evaluations. Conversely, Arbor’s lower development score of 72.22 was complemented by a higher holdout score of 77.36, indicating its results are applicable in real-world scenarios.
Additionally, during a cross-task transfer experiment post-optimization of the BrowseComp task, researchers tested the improved codebase on two unrelated search tasks, HLE and DeepSearchQA. Arbor’s optimized codebase led to significant performance enhancements on these unknown tasks as well.
Implementing Arbor: Opportunities and Challenges
For engineering leaders considering Arbor’s integration into their existing technology stack, the framework is intended to complement current Git workflows rather than replace them. Jin noted, “The output generates a standard git branch that existing code review, CI, and human evaluations can evaluate directly.” Only verified results are merged into the main trunk, thereby preserving the integrity of the central repository until a developer opts to promote the code.
However, the implementation of Arbor does have its complexities. Jin points out that the most significant concern is token costs, as the continuous operation of a long-term coordinator managing the tree and deploying executors incurs considerable expense. Running multiple separate worktrees simultaneously also demands substantial computing and storage resources.
So, what are Arbor’s ideal use cases? According to Jin, it thrives on tasks with clear, reliable metrics, an allowance for prolonged timelines, and a legitimate search space containing various feasible avenues, such as pipeline optimization, data synthesis quality, and model training enhancements.
Conversely, teams should refrain from utilizing Arbor for tasks with real-time demands, trivial one-line fixes, or during circumstances where the underlying evaluation metrics are questionable. The overall success of the run is closely tied to the evaluator’s quality. “If the metric isn’t trustworthy, Arbor will simply optimize towards unreliable outcomes quicker,” Jin cautioned.
Jin envisions a future evolution that surpasses singular scalar metrics. “A natural progression would be for each node’s artifact to encompass a vector — accuracy, latency, cost — instead of just a single score,” he said. “Transitioning from single scalar optimization to a multi-objective Pareto search is a logical extension of this framework.”