Fish Audio Secures $50M Seed Funding to Develop AI Voice Solutions for Creators and Businesses

The demand for AI-generated voice technology is substantial. Innovative applications require these voice models to exhibit greater expressiveness, while businesses aiming to enhance customer service and sales operations need more customizable options.
Based in Palo Alto, Fish Audio is poised to meet these diverse needs with a collection of over 15,000 natural language controls. Since its inception last year, the startup has attracted more than 8 million users to its open-source and hosted voice models, generating an impressive annual recurring revenue of $21 million.
To capitalize on this momentum, the company recently announced it has secured $50 million in a seed funding round led by Coreline Ventures and Capital Today, with additional support from several investors including 359 Capital, Parable, and HF0.
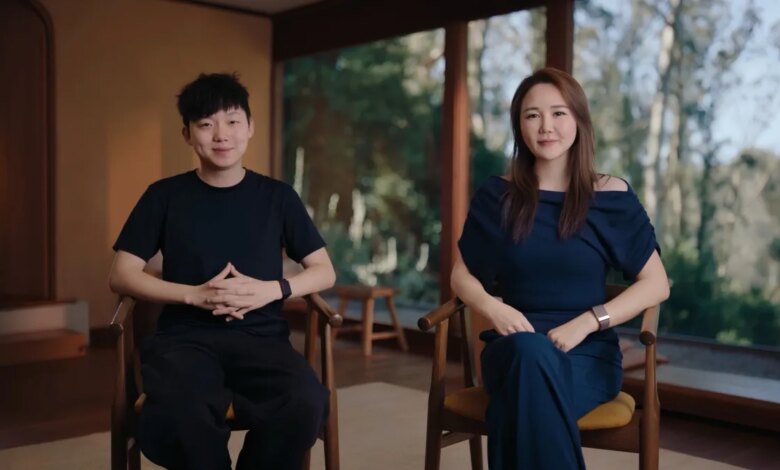
Fish Audio was founded by Shijia Liao, a former NVIDIA researcher. Frustrated with the lack of expressive synthetic voices available, Liao developed a voice generation model using a single GPU and made it open-source. The Fish Speech repository on GitHub has now amassed over 31,000 stars, becoming a valuable resource for indie developers, game designers, and other creators.
In its first year, Fish Audio released five models, including four for speech generation and one for speech-to-text. While three of the speech generation models are open-source, the latest version, S2.1 Pro, is available exclusively through a paid API.
The company offers subscription plans for individual creators and teams, which provide a designated amount of generation time and include voice cloning capabilities. An enterprise version of their platform is also available, already utilized by companies like HeyGen and Sanas.
“Each business has unique needs and preferences,” said Cao. “For instance, HeyGen focuses on realistic voices for AI avatars, while gaming studios seek expressive character voices, and companies like LiveKit require natural-sounding voices with low latency for calls.”
Fish Audio has expanded its voice library by encouraging users to submit their voices for model training, providing compensation for those featured. However, this approach led to some issues when certain creators claimed their voices were used without permission. Although the company established a DMCA takedown process, it was slow and inefficient.
In response, CEO and co-founder Rissa Cao stated that the takedown process has now been automated. Creators can promptly submit a voice sample or a contract to verify ownership and have their voice removed within minutes, although issues can still arise if voices are uploaded without the artist’s knowledge before they can act.
Oskue Honda of Coreline Ventures emphasized the importance of trust in a community-driven model. “Such an approach can only be sustainable if creators have faith in the platform, meaning that consent, transparency, and attribution must be integral to the product,” he remarked.
Cao mentioned that when Fish Audio was primarily an open-source initiative, it functioned efficiently without needing external funding. However, to develop advanced models and attract enterprise clients, the company sought investment.
Looking ahead, Fish Audio plans to unveil an audio understanding model this year, as well as a speech-to-speech model.
The voice generation market is becoming increasingly competitive, with notable companies such as ElevenLabs and Speechify vying for attention from creators and enterprises.
Rico Mallozzi from 359 Capital commented on Fish Audio’s competitive edge. “Their ability to create state-of-the-art models with limited resources is remarkable and highlights their technical skill in bridging the gap between artificial and human-like voices,” he noted during a recent call.