Revolutionary Agentic Memory Model Utilizes 118K Tokens Per Query, While LangMem Executes 3.26M Tokens

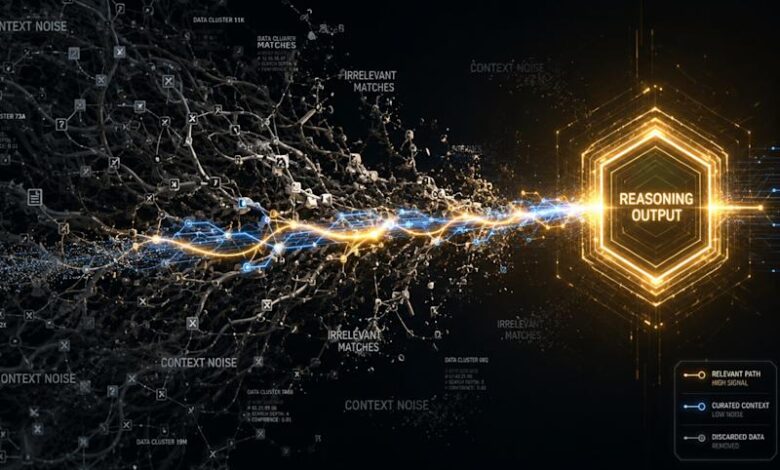
Recent advancements in AI have highlighted a significant limitation of AI agents: their context windows quickly become saturated, leading to the retrieval of irrelevant data. In response, researchers from the National University of Singapore have created MRAgent, a novel framework that moves away from the traditional “retrieve-then-reason” paradigm, favoring a dynamic memory enhancement based on accumulating information.
This approach integrates multi-step memory reconstruction into the reasoning capabilities of large language models (LLMs). MRAgent distinguishes itself by significantly lowering token usage and runtime expenses when compared to other memory management systems.
The limitations of passive data retrieval in extensive tasks
Conventional retrieval systems typically use vector searches or graph traversals to pull documents, which are then analyzed by an LLM. However, this passive method has notable weaknesses, leading to three main challenges:
-
These systems lack the ability to adjust their retrieval strategies during reasoning. For instance, if an agent retrieves a document and realizes it omitted an essential detail—like a date or a person—it cannot issue a follow-up query based on that insight.
-
Fixed similarity scores and predefined graph paths provide only superficial matches, cluttering the LLM’s context with irrelevant information, which impairs reasoning capabilities.
-
Current systems are heavily reliant on established structures such as top-k results and fixed relevance functions, stifling the adaptability necessary for unpredictable, long-term user interactions.
The researchers contend that overcoming these obstacles requires a transition to an “active and associative reconstruction process,” drawing inspiration from cognitive neuroscience.
This new paradigm enables memory retrieval to occur sequentially rather than simply pulling from a static database. The system starts with specific cues from user prompts, such as names or locations, which guide it toward related concepts instead of overwhelmed by large text blocks.
The agent then collects small pieces of evidence gradually, using each new detail to inform its next steps until it comprehensively reconstructs the desired narrative.
Implementation of active memory reconstruction in MRAgent
MRAgent (Memory Reasoning Architecture for LLM Agents) conceptualizes memory as an interactive framework. When tasked with complex queries, the agent employs the core reasoning abilities of the LLM to navigate various retrieval paths within a structured memory graph.
During this process, the LLM evaluates the evidence it accumulates and refines its search iteratively. It formulates new constraints, focuses on the most informative paths, and discards less relevant options. This enables MRAgent to uncover hidden information while minimizing noise in the LLM’s context.
-
Cues: Detailed keywords and contextual attributes extracted from user prompts.
-
Content: The stored memory units, categorized into layers like episodic memory for specific events and semantic memory for general facts and user preferences.
-
Tags: Semantic links that summarize relationships between specific Cues and Content.
This structuring allows for a swift two-stage retrieval process. The LLM first identifies candidate Tags based on Cues. As Tags represent the semantic relationships in the data, they facilitate quick assessments of relevance, enabling the agent to identify promising paths and eliminate irrelevant ones before accessing comprehensive memory records.
For example, if a user inquires, “How did Nate use the prize money from his third video game tournament?” the following steps unfold:
-
MRAgent identifies cues like “Nate,” “video game tournament,” and “win.”
-
The agent maps these cues to the memory graph and considers associated Tags like “Tournament Victory” and “Tournament Participation,” focusing only on the victory tag.
-
It retrieves specific episodic memories related to the selected Cue-Tag pair, pinpointing three distinct instances of Nate winning.
-
The agent evaluates the three memories, selects the most relevant one, and discards the others.
-
From this, it updates its cues and embarks on further exploration using newly derived information, repeating the process to gather adequate responses, ultimately concluding that “Nate saved the money.”
MRAgent’s performance in benchmarks
MRAgent functions alongside various memory frameworks, including A-MEM, MemoryOS, LangMem, and Mem0. The team assessed MRAgent using the LoCoMo and LongMemEval industry benchmarks, which evaluate long-horizon queries across multiple sessions of dialogue. The tests employed Gemini 2.5 Flash and Claude Sonnet 4.5 as foundational models.
Results indicate that MRAgent outperformed all comparative frameworks across question types by a significant margin.
Moreover, when considering operational cost, MRAgent minimized prompt token usage to 118k per sample in LongMemEval, while A-Mem utilized 632k tokens and LangMem reached 3.26 million tokens for a single query. MRAgent also reduced compute time significantly, halving runtime compared to A-Mem from 1,122 seconds to 586 seconds.
MRAgent’s efficiency stems from its on-demand mechanics, allowing the evaluation of tags and the discarding of unnecessary paths before data retrieval, which optimizes cost and context usage. The system is capable of assessing its gathered information and recognizes when to halt further searches, thus avoiding unnecessary data exploration.
Implementation and developmental considerations
Despite the efficacy of MRAgent, the Cue-Tag-Content structure requires setup prior to querying. Developers must design the underlying memory database to allow efficient navigation and pruning without incurring excessive computational costs.
Fortunately, manual data labeling is unnecessary, as MRAgent incorporates an automated pipeline that uses LLMs to process raw user interaction histories and automatically populate its memory graph. Developers primarily need to set up an ingestion pipeline that routes raw user interactions through prompt templates to extract metadata before storing it in the graph database.
This ingestion process is lightweight, as the authors emphasize that MRAgent aims to maintain simplicity in data construction.
The code for MRAgent has been made available for public access.