PrismML, an artificial intelligence laboratory, is gaining attention not for its funding total—having raised a modest $22.25 million in its seed round—but for the innovative technology and exceptional talent behind it.
The company aims to prove that highly capable large language models (LLMs) don’t necessarily need to be enormous to be effective.
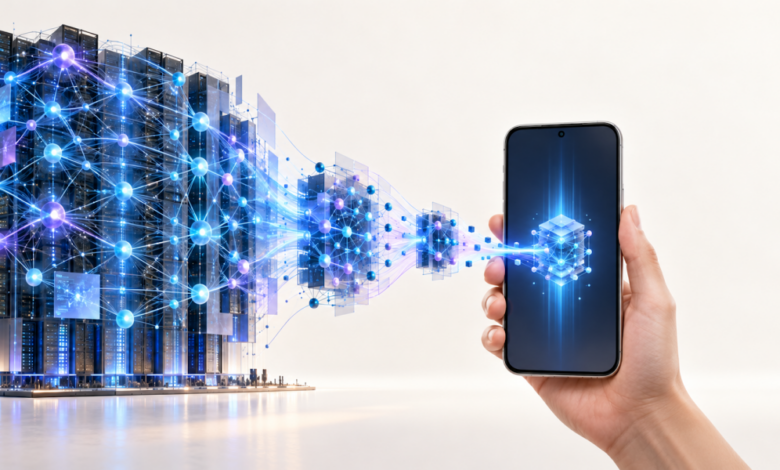
PrismML is focused on creating reasoning models that are compact enough to run on typical PCs and smartphones. There are even speculations about potential collaborations with Apple, although CEO Babak Hassibi did not confirm this information.
On Thursday, PrismML unveiled Bonsai 2 27B, its latest model. This version simplifies Qwen3.8 27B, a popular open-source model from Alibaba, compressing it to just 5.9 GB. This size allows it to be used on personal computers and possibly high-end mobile devices, representing a significant 9x to 10x decrease in memory usage compared to the original model.
Founded by researchers from Caltech and led by Hassibi, a professor there who specializes in compression technology, PrismML also benefits from the expertise of advisor Ion Stoica. Stoica, a co-founder of Databricks and director of Berkeley’s Sky Computing Lab, has been instrumental in developing numerous successful technologies and startups.
The startup’s investors include Khosla Ventures, Cerberus Capital, and Caltech.
PrismML is not alone in its pursuit of LLM compression technology; other companies like Multiverse Computing, founded by a notable academic from Spain, are also in this space and have secured significant funding.
Hassibi claims that PrismML’s compression methods yield unique results, as the performance of its LLMs remains virtually unaffected. The Bonsai 2 model hits 98% of Qwen’s overall benchmark scores, an improvement over the original Bonsai model released earlier this year, which achieved 95%. The initial version of Bonsai has seen over 11 million downloads, with even smaller models achieving an additional 2.6 million downloads.
This progression illustrates the enhancement in PrismML’s compression technology over time. However, the possibility of reaching perfect benchmark parity is uncertain. Hassibi acknowledges that some reduction in performance is likely to persist with compression techniques.
Nevertheless, the significance of achieving complete benchmark parity is somewhat theoretical. Given that LLMs exhibit inaccuracies even in their uncompressed states, and benchmarks may not fully capture real-world performance, a slight degradation might not severely impact the model’s practical applications. Additionally, the software environment in which the model operates also significantly influences accuracy.
PrismML’s innovative approach involves reducing the “weights” in a model, which represent the knowledge acquired during training. Traditionally, these weights use 16 bits, but the company’s “ternary” weights condense this down to three values: +1, −1, or 0. This reduction allows for substantial space savings.
PrismML’s future ambition is to apply its compression techniques to even larger models. “We plan to release models in the several-hundred-billion-parameter range in the coming months, and I anticipate it will be simpler to maintain their intelligence,” Hassibi noted.
He further explained that increasing model sizes create more opportunities for effective compression without intelligence loss. “In general, larger models allow for easier achievement of perfect compression,” he added.
Stoica expressed enthusiasm for this technology, emphasizing its potential to run sophisticated models directly on end-user devices. “You’ll have advanced intelligence accessible anytime, and it will be free, running on your own device, ensuring privacy since it won’t rely on cloud-based operations.”